 Reading bench
Compared with Artificial Analysis
Artificial Analysis's Decision Index models, on our benchmark
Our five reply charts
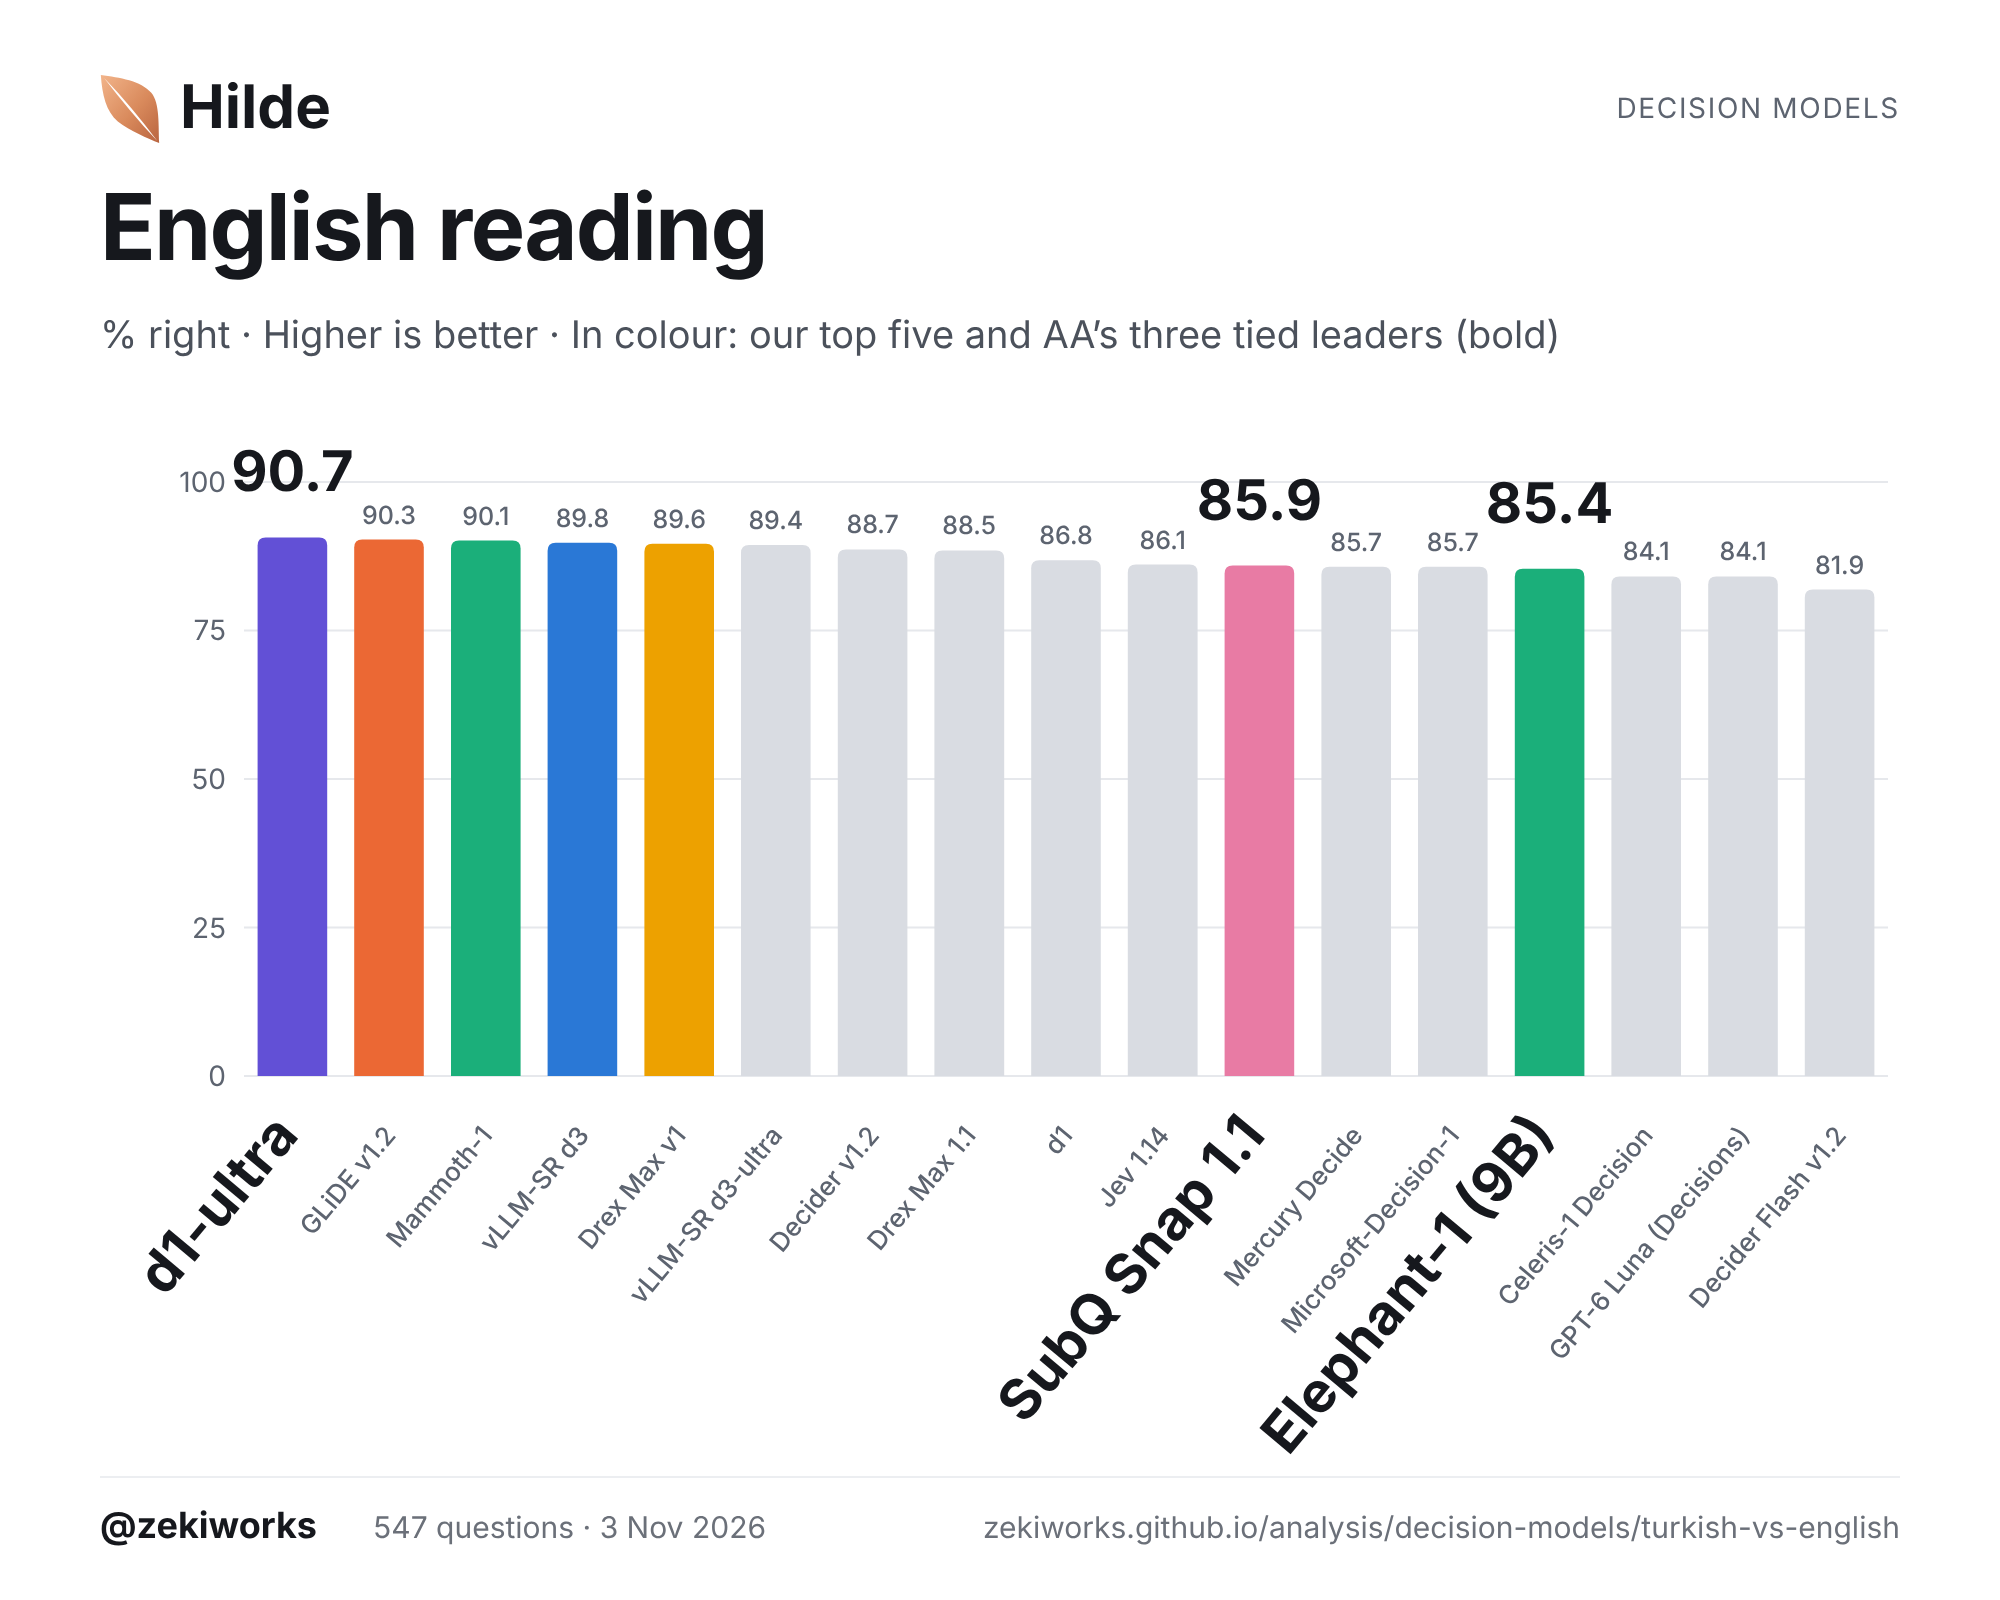
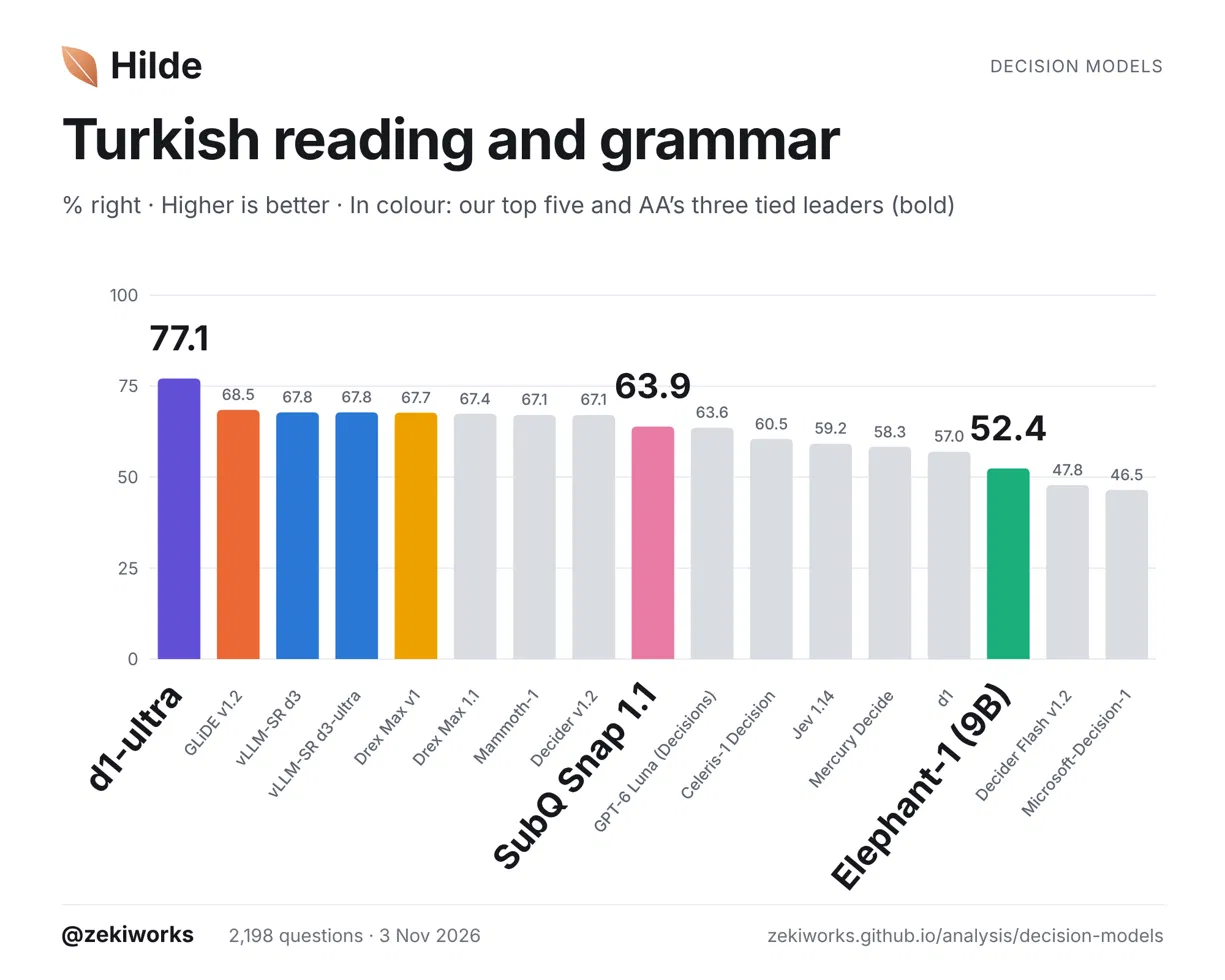
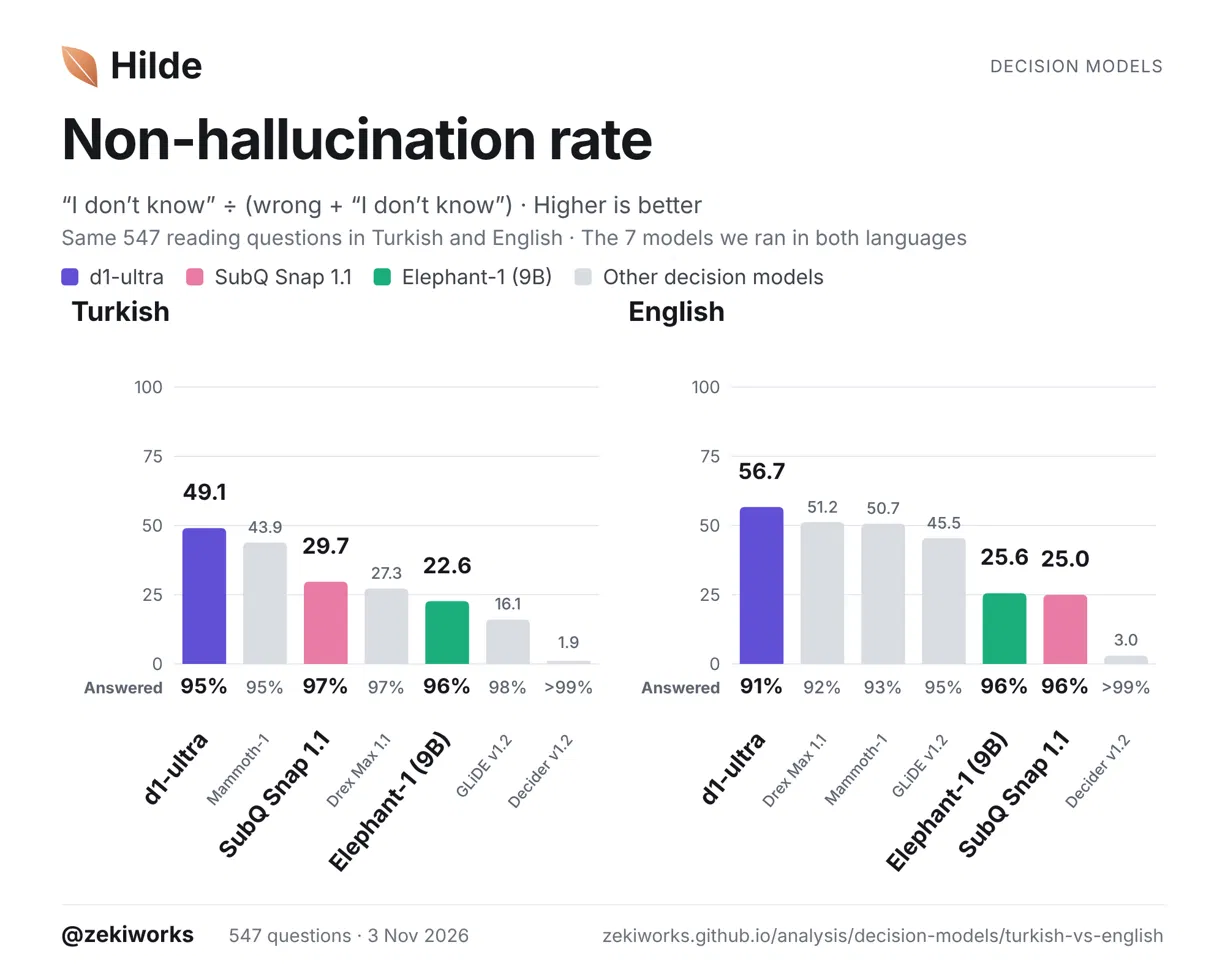
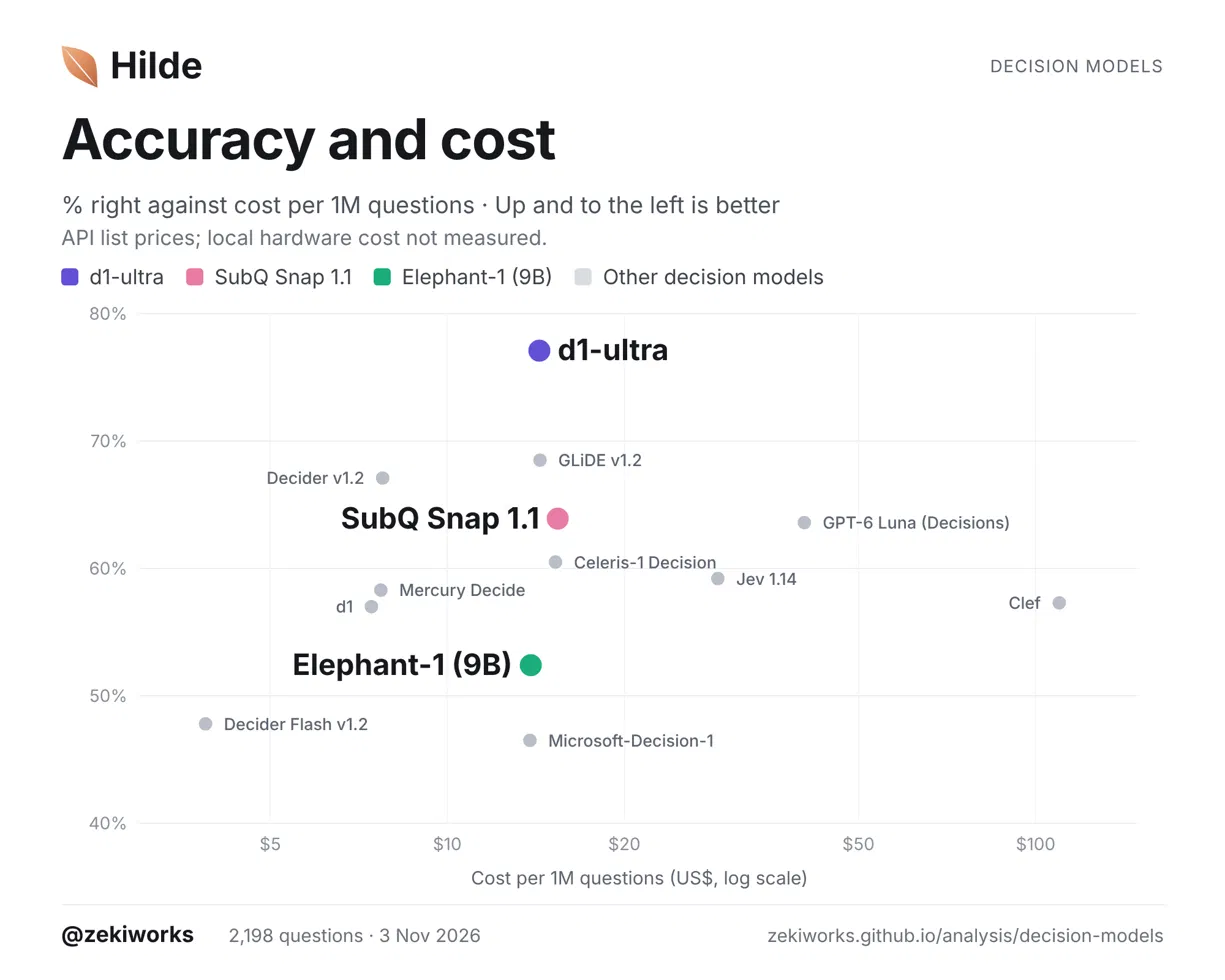
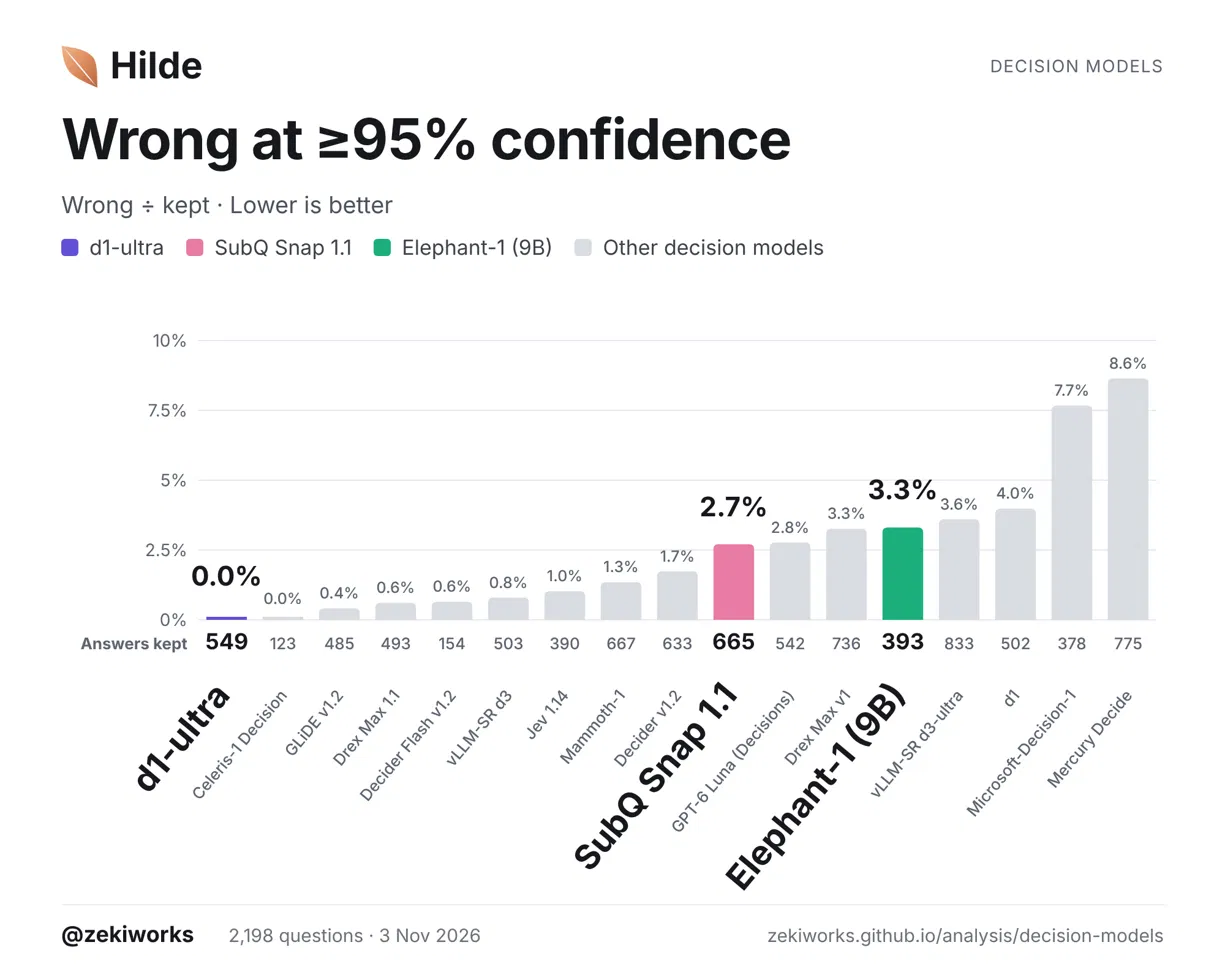
Our numbers for 13 of the 14 decision models of Artificial Analysis's Decision Index v1.0; our tests differ from theirs, so the two rank different things.
The cards of our thread on X in reply to Artificial Analysis's post, in the thread's order (results 8f69ed8d); each opens as an image.
Artificial Analysis does not name its GLiDE version. The rest of this page uses Fastino's hosted GLiDE; the cards show GLiDE v1.2, which we ran on our GPU.
Accuracy
Share of the Text tab's 2,198 questions answered right · higher is better
Decision models: worst 46.5%best 77.1% (higher is better)
Non-hallucination rate
“Bilmiyorum” among the answers that were not right, with it offered as a sixth option (the Hallucination tab); beside it the share answered and the error rate among the answers · higher non-hallucination is better, read with the share answered
Decision models: worst 0.3%best 75.1% (higher is better) Not run with “Bilmiyorum”: GPT-6 Luna · Decisions API, celeris-1-decision, Jev 1.14, Mercury Decide, d1 and Microsoft-Decision-1.
Cost per 1M questions
Estimated from list prices and the token use recorded in each run, in US dollars per 1 million questions (the Text tab gives it per 1,000 questions) · lower is better
Decision models: worst $160best $4 (lower is better) Costs: API list prices and recorded token use. Setups on our own GPUs: the maker's list price for the same model (each value's tooltip names it); our hardware cost is not measured.
Median latency per request
Time from sending one request to its answer, measured from our computer: on our GPU for the setups run there, through the network for the APIs (with OpenRouter’s time for those via OpenRouter) · lower is better
Decision models: worst 2.09 sbest 0.074 s (lower is better) GPT-6 Luna · Decisions API and GLiDE · API sent 4 requests at a time; the others one.
Every number, model by model
Ranked by accuracy. Accuracy, reading and grammar: each model's run on the Text tab, one question per request, on all its questions and on each part. Page images: the Page images tab, the page's picture alone (condition B). Non-hallucination and attempt rates: the Hallucination tab, each model's first run (d1-ultra and GLiDE · API have five; that tab gives their range). Cost: estimated from list prices and the token use recorded in each run, per 1,000 questions as on the Text tab, and the same times 1,000 for comparison with Artificial Analysis's cost per 1 million tasks. Artificial Analysis's Elephant 9B is Base Labs' elephant-1, our Elephant-1.
| Model | Accuracy2,198 questions; higher is better | Reading656 questions; higher is better | Grammar1,542 questions; higher is better | Page images, picture alone763 questions; higher is better | Non-hallucinationof answers not right, % “Bilmiyorum” · higher is better | Answerednot “Bilmiyorum”: (right + wrong) / 2,198 | Error rateof its answers: wrong / (right + wrong) · lower is better | Cost per 1,000 questionsestimated; lower is better | Cost per 1M questionsthe same, × 1,000; lower is better | Median latency per requestseconds; lower is better |
|---|---|---|---|---|---|---|---|---|---|---|
| d1-ultraArtificial Analysis: d1-ultra | 77.1%1,694 of 2,198 | 92.1%604 of 656 | 70.7%1,090 of 1,542 | 50.1%382 of 763 | 75.1%617 “Bilmiyorum” of 822 not right | 71.9%1,581 of 2,198 answered | 13.0% | $0.014 | $14 | 0.223 s |
| GLiDE APIArtificial Analysis: GLiDE | 67.9%1,492 of 2,198 | 87.8%576 of 656 | 59.4%916 of 1,542 | Not measured | 59.4%521 “Bilmiyorum” of 877 not right | 76.3%1,677 of 2,198 answered | 21.2% | $0.160 | $160 | 2.09 s4 in flight |
| Perplexity Decider 27B v1.2 DGX SparkArtificial Analysis: Decider v1.2 | 67.1%1,474 of 2,198 | 89.2%585 of 656 | 57.7%889 of 1,542 | No image input | 0.3%2 “Bilmiyorum” of 719 not right | 99.9%2,196 of 2,198 answered | 32.7% | $0.008 | $8 | 0.580 s |
| SubQ Snap 1.1Artificial Analysis: SubQ Snap 1.1 | 63.9%1,404 of 2,198 | 87.0%571 of 656 | 54.0%833 of 1,542 | 45.7%349 of 763 | 47.1%437 “Bilmiyorum” of 927 not right | 80.1%1,761 of 2,198 answered | 27.8% | $0.015 | $15 | 0.378 s |
| GPT-6 Luna Decisions APIArtificial Analysis: GPT-6 Luna (Decisions) | 63.6%1,398 of 2,198 | 85.5%561 of 656 | 54.3%837 of 1,542 | 32.6%249 of 763 | Not run | Not run | Not run | $0.040 | $40 | 0.191 s4 in flight |
| celeris-1-decisionArtificial Analysis: Celeris-1 Decision | 60.5%1,329 of 2,198 | 85.2%559 of 656 | 49.9%770 of 1,542 | Not measured | Not run | Not run | Not run | $0.015 | $15 | 0.401 s |
| Jev 1.14Artificial Analysis: Jev 1.14 | 59.2%1,301 of 2,198 | 85.1%558 of 656 | 48.2%743 of 1,542 | 43.3%330 of 763 | Not run | Not run | Not run | $0.029 | $29 | 0.211 s |
| Mercury DecideArtificial Analysis: Mercury Decide | 58.3%1,281 of 2,198 | 84.5%554 of 656 | 47.1%727 of 1,542 | Not measured | Not run | Not run | Not run | $0.008 | $8 | 0.313 s |
| ClefArtificial Analysis: Clef | 57.3%1,259 of 2,198 | 85.1%558 of 656 | 45.5%701 of 1,542 | Not measured | 7.4%71 “Bilmiyorum” of 965 not right | 96.8%2,127 of 2,198 answered | 42.0% | $0.110 | $110 | 0.205 s |
| d1Artificial Analysis: d1 | 57.0%1,253 of 2,198 | 82.8%543 of 656 | 46.0%710 of 1,542 | Not measured | Not run | Not run | Not run | $0.007 | $7 | 0.305 sits repeat runs |
| Elephant-1Artificial Analysis: Elephant 9B | 52.4%1,151 of 2,198 | 80.5%528 of 656 | 40.4%623 of 1,542 | Not measured | 34.8%405 “Bilmiyorum” of 1,163 not right | 81.6%1,793 of 2,198 answered | 42.3% | $0.014 | $14 | 0.074 s |
| Perplexity Decider Flash v1.2Artificial Analysis: Decider Flash v1.2 | 47.8%1,050 of 2,198 | 72.7%477 of 656 | 37.2%573 of 1,542 | Not measured | 14.7%180 “Bilmiyorum” of 1,224 not right | 91.8%2,018 of 2,198 answered | 51.7% | $0.004 | $4 | 0.132 s |
| Microsoft-Decision-1Artificial Analysis: Microsoft-Decision-1 | 46.5%1,021 of 2,198 | 73.5%482 of 656 | 35.0%539 of 1,542 | Not measured | Not run | Not run | Not run | $0.014 | $14 | 0.286 s |
- Costs: API list prices and recorded token use. Setups on our own GPUs: the maker's list price for the same model (each value's tooltip names it); our hardware cost is not measured.
- GLiDE · API: at the price recorded on 8 October 2026. Provider update: $0.04 per 1M input tokens since, as listed on 22 October 2026.
- d1: its free tier, priced at Liquid's list price for the same model.
- Latency: the median time per request. Local setups ran on our hardware, listed on each setup’s page; API latency includes the network, and via OpenRouter, OpenRouter’s time.
- d1: latency from its repeat runs (runs 66, 94, 105 and 108), 0.305 s median per request.
Artificial Analysis's post of 22 October 2026 ranks 14 decision models on its Decision Index v1.0, a weighted average of four of its own evaluations (AA-Omniscience-Decision, HLE-MultiChoice, When2Call and WildGuardTest). 13 of them are on our leaderboard; Clef-Omni is not. This page gathers our numbers for those 13, from our published results, and opens with our reply charts. It ranks nothing new and changes no number on the other pages.
Download: results.json (the Text and Hallucination tabs' numbers) and vision.json (the Page images tab's).